 Starvard
Shipped by Vibes: The Real State of AI Code Generation in 2026
AI coding tools are producing the fastest revenue ramps in software history, and some of the most sobering research findings too. Here is who is actually shipping, what the best evidence says about speed, and exactly where the approach breaks.
If you want one fact that captures the AI coding boom, take this one. Lovable, a Stockholm startup whose product builds whole apps from plain-language prompts, crossed $100 million in annual recurring revenue in July 2025, eight months after launch, with 45 employees. TechCrunch called the pace one of the fastest ever recorded for a software company. Four months later Lovable had doubled to $200 million. In December 2025 it raised $330 million at a $6.6 billion valuation.
That is the top of the market. The interesting question for 2026 is not whether AI code generation is big. It is what holds up when you look past the revenue charts: at the controlled studies, the security audits, and the apps that got hacked within days of launch. The honest picture is stranger and more useful than either the hype or the backlash.
First, how the code actually gets made
Everything in this article makes more sense with a clear picture of the machinery, so here it is in brief. An AI coding tool is two things stacked together: a large language model, trained on vast amounts of public code and text until it became very good at predicting what code usually comes next, and a harness of ordinary software around the model that feeds it context and checks its work.
The stack has three levels, and the industry climbed all three in about four years.
Autocomplete works at the scale of the next few lines. You type, the model predicts, you accept or ignore. You remain the author. The model is a very learned guesser looking over your shoulder.
Chat generation works at the scale of a function or a file. You describe what you want in words, and the model writes the whole block into a chat window, which you then carry into your project yourself. At this level the human is the courier between the model and the code, and also the only test suite.
Agents work at the scale of a task. You state a goal ("add password reset, and email the user a link"), and the harness lets the model open files across the project, write and edit code in several places, run the test suite, read the failures, and loop until the tests pass or it gets stuck. The model's raw ability changed less between these levels than the results did. What changed is who closes the loop between writing code and finding out whether it works.
Watch: The Secrets of Claude Code From the Engineers Who Built It, from Every. Boris Cherny and Cat Wu, who built the best-known coding agent, explain how the loop and its sub-agents actually work, which is level three described by the people who shipped it.
Two consequences follow, and both matter for reading the evidence below. First, an agent is only as good as the checks you give it. A project with strong automated tests gives the loop something true to aim at. A project with no tests lets the model declare victory over code that nobody verified. Second, headline capability numbers always describe a system, never just a model: the same model, given better tools, more attempts, and a stricter harness, scores very differently. Benchmark results in this field are real, but they are measurements of a model plus its equipment.
The scoreboard: who is shipping, and how fast
Start with the toolmakers, because their numbers are the clearest evidence that working software is being produced this way at scale.
- Lovable. Beyond the revenue above, the company reported more than 100,000 new projects built on its platform every day, and more than 25 million projects created in its first year. Its customers include Klarna, Uber, and Zendesk. Co-founder Anton Osika first built the open source GPT Engineer in 2023.
- Cursor (Anysphere). The AI code editor founded by four MIT graduates passed $1 billion in annualized revenue in November 2025, the same month it raised $2.3 billion at a $29.3 billion valuation.
- Claude Code (Anthropic). Anthropic disclosed in December 2025 that its terminal-based coding agent had reached a $1 billion annualized revenue run rate in November, roughly six months after becoming generally available in May 2025. It had passed $500 million by September.
- Replit. The browser-based coding platform said its annualized revenue grew from $2.8 million to $150 million in less than a year, as it pivoted to letting users build apps by describing them.
- GitHub Copilot. The original AI pair programmer, launched in 2021 as a humble autocomplete, passed 20 million users in July 2025, a figure Microsoft's CEO gave on an earnings call. It remains the quiet giant of the category: less discussed than the agent startups, larger than all of them.
The products built with these tools can move fast too. Pieter Levels, a well-known independent maker with no game development experience, built a browser flight simulator called fly.pieter.com in about three hours using Cursor in February 2025. According to Snyk's account of the project, it earned $38,000 in its first 10 days, was running at roughly $87,000 a month by day 20, and reached 320,000 players. And at Y Combinator, as our companion post describes, a quarter of the Winter 2025 startup batch reported codebases that were 95% AI-generated.
None of this proves the code is good. It proves something narrower and still remarkable: people are shipping real products, with real paying customers, at a speed that had no precedent two years ago.
Inside the giants: the percentages nobody expected
The startups are not the only ones building this way. Two of the most revealing figures in the industry come from the largest incumbents, stated on the record by their own chief executives.
At Google, CEO Sundar Pichai said on the company's October 2024 earnings call that more than a quarter of all new code at Google was generated by AI, then reviewed and accepted by engineers. A year later, the figure he gave was nearly half. By April 2026, speaking at the Google Cloud Next conference, he put it at 75% of new code: AI-generated, and approved by engineers. Read the trend, not just the level. In about eighteen months, the default first author of new code at one of the world's largest engineering organizations flipped from human to machine, and the humans moved to the review chair.
At Microsoft, CEO Satya Nadella said in April 2025, on stage at Meta's LlamaCon conference, that "maybe 20%, 30% of the code that is inside of our repos today and some of our projects are probably all written by software," adding that results were stronger in Python than in C++. In the same conversation, Meta's Mark Zuckerberg said his bet was that within about a year, "maybe half the development is going to be done by AI, as opposed to people, and then that will just kind of increase from there."
These numbers deserve one honest caution. Each company counts differently: new code versus all code, generated versus accepted, and none of them publish the counting method. Treat the figures as directional, not exact. But direction is what strategy is made of, and three of the largest software organizations on Earth are pointing the same way.
What the best evidence says about speed
Here the story splits, and the split is the most important thing in this article.
On one side: controlled experiments on well-defined tasks show large gains. In the best-known early trial, published by researchers including GitHub staff in 2023, developers using GitHub Copilot finished a from-scratch web server task about 56% faster than a control group. Anthropic has also reported on its own engineers: in a company study of 132 staff, engineers said they used Claude in about 60% of their work and estimated their own productivity gains at roughly 50%. That figure is self-reported by the vendor's own team, so treat it as a claim, not a measurement.
On the other side sits the most rigorous independent study in the field. In July 2025, the research nonprofit METR published a randomized controlled trial: 16 experienced open source developers, working on 246 real issues in large codebases they had maintained for years, with each issue randomly assigned to allow or ban AI tools. The result ran against everyone's expectations. With AI allowed, developers took 19% longer. They had predicted AI would speed them up by 24%. Afterward, having actually been slowed down, they still believed it had made them 20% faster.
Two honest caveats belong with that study. METR itself warns that its setting, experts working in mature codebases with high quality bars, is not most programming. And when METR tried to repeat the experiment with newer tools, it reported in February 2026 that the follow-up could not produce a reliable number, partly because so many developers no longer wanted to work without AI at all, and some held back tasks rather than do them unaided. METR's own reading is that developers are probably sped up more now than in early 2025, but the broken experiment means nobody can say by how much.
Watch: AI Made Developers Slower, Then Something Weirder Happened, from Inside The Build. It walks through the trial, the perception gap, and the follow-up study that broke down because developers no longer wanted to work without the tools.
The organizational data adds a wrinkle that fits METR's result rather than contradicting it. DORA, Google's long-running research program on software delivery, surveyed nearly 5,000 technology professionals for its 2025 report on AI-assisted development. It found AI adoption now clearly associated with higher delivery throughput: teams ship more, more often. It also found adoption still associated with higher instability: more failed changes and more rework. DORA's own summary of the pattern is the single most useful sentence in this field: AI is an amplifier. It magnifies what a team already is. Strong teams with good tests and clean systems get faster. Struggling teams get their struggles at higher speed. That is precisely what a tool would do if it multiplied output without multiplying judgment.
Put the pieces together and a pattern emerges. AI generation is fastest where the task is new, self-contained, and easy to check: a prototype, a landing page, a data script, a first version. It is slowest, and sometimes negative, where the task lives inside a large existing system with unwritten rules. The feeling of speed, METR showed, is not evidence of speed. Teams that measure get the benefit. Teams that vibe on feelings get the invoice.
The capability curve underneath everything
Why did all of this ignite in 2025 rather than 2022? Because a measurable capability curve crossed a usefulness line, and you can watch it happen in the benchmarks.
The field's favorite yardstick is SWE-bench, which tests systems on real bug reports from real open source projects: read the issue, find the fault, write a fix that passes the project's own tests. When the benchmark was introduced in late 2023, the best model its creators tested, Claude 2, resolved 1.96% of the problems. On the human-checked Verified edition, leading systems were resolving about half the tasks by early 2025, and by late 2025 the top entries on the official leaderboard were at roughly three quarters or more, up to about 79%. In two years the test went from nearly impossible to mostly handled by the best systems.
METR measures the same climb from a different angle: not scores, but task length. Its researchers time how long human experts need for a software task, then find the length at which an agent succeeds half the time. That horizon, they reported in March 2025, has been doubling roughly every seven months since 2019. The best model they had tested at that point could handle tasks of about an hour of human work at that coin-flip reliability. Tasks of a few minutes were solved almost every time. Tasks beyond roughly four hours of human effort succeeded less than 10% of the time. A doubling clock like that explains a lot of confusing arguments. Last year's "it cannot do real work" and this year's "it just did my whole sprint" can both be honest reports from honest people. They are describing different points on a fast-moving curve.
Hold the caveats alongside the numbers. Benchmarks leak: the SWE-bench issues are public and old, model makers train on public data, and in February 2026 OpenAI stopped reporting SWE-bench Verified results, citing contamination and flawed tests among its reasons. And a 50% success horizon is a coin flip, not a colleague: the task length at which agents succeed 80% of the time is several times shorter. The curve is real. So is the gap between a leaderboard and your codebase, which is why the next two sections, on what breaks, are not footnotes to the success story. They are half of it.
Where it breaks, part one: security
The hardest numbers in this field come from Veracode's 2025 GenAI Code Security Report. Veracode tested more than 100 large language models on 80 coding tasks in Java, Python, C#, and JavaScript. In 45% of cases, the generated code introduced a security flaw from the OWASP Top 10, the standard list of the most critical web application risks. Java failed 72% of the time. On tasks prone to cross-site scripting, the models failed to defend against the attack in 86% of cases. And the finding that should end a common assumption: newer, larger models were not meaningfully better at writing secure code than older ones. Capability went up. Security stayed flat.
What that looks like in the wild arrived within weeks of the term "vibe coding" going viral. In March 2025, security researchers examined 1,645 apps showcased on Lovable's own platform and found 170 of them, about one in ten, missing the database access rules (Supabase row level security) that keep one user's data separate from another's. Names, email addresses, financial details, and API keys were reachable without authentication. The flaw was serious enough to receive its own identifier, CVE-2025-48757. The root cause was a pattern, not a single mistake: the AI did not set up the access rules unless asked, and the people building the apps did not know to ask.
The human version of the same story played out in public. A founder named Leo built his subscription product, Enrichlead, entirely with Cursor and posted proudly in March 2025 that it contained zero hand-written code and that people were paying for it. Two days later he posted again: "guys, i'm under attack." Attackers maxed out his API keys, bypassed the paywall, and filled his database with junk, exploiting gaps an experienced developer would have closed by default, such as authentication checks and rate limits. Unable to fix code he had never read, he later shut the product down.
There is also a newer, quieter risk. A March 2025 study of 576,000 AI-generated code samples found that 19.7% of the software packages the models told developers to install did not exist. Attackers can register those invented names and wait for the next developer to install them, a technique researchers call slopsquatting. The poison enters through the supply chain, typed by the victim's own hands.
Where it breaks, part two: the code you have to live with
Security failures announce themselves. Maintenance failures compound silently, and the data here is younger but pointing one way. GitClear analyzed 211 million lines of code from real repositories and found that in 2024, for the first time, copy-pasted lines outnumbered lines that were moved or refactored, long the normal hygiene of a codebase. Blocks of five or more duplicated lines rose roughly eightfold that year. AI assistants are eager to write a fresh function and poor at noticing the similar one that already exists, so codebases grow by duplication, and every copy is a place a future fix has to be made more than once.
Developers feel this before they can measure it. In the Stack Overflow 2025 survey, the top frustration with AI tools, named by 66% of respondents, was answers that are "almost right, but not quite," and 45% said debugging AI-generated code is more time-consuming than expected. Code that looks right and is nearly right is the most expensive kind to own.
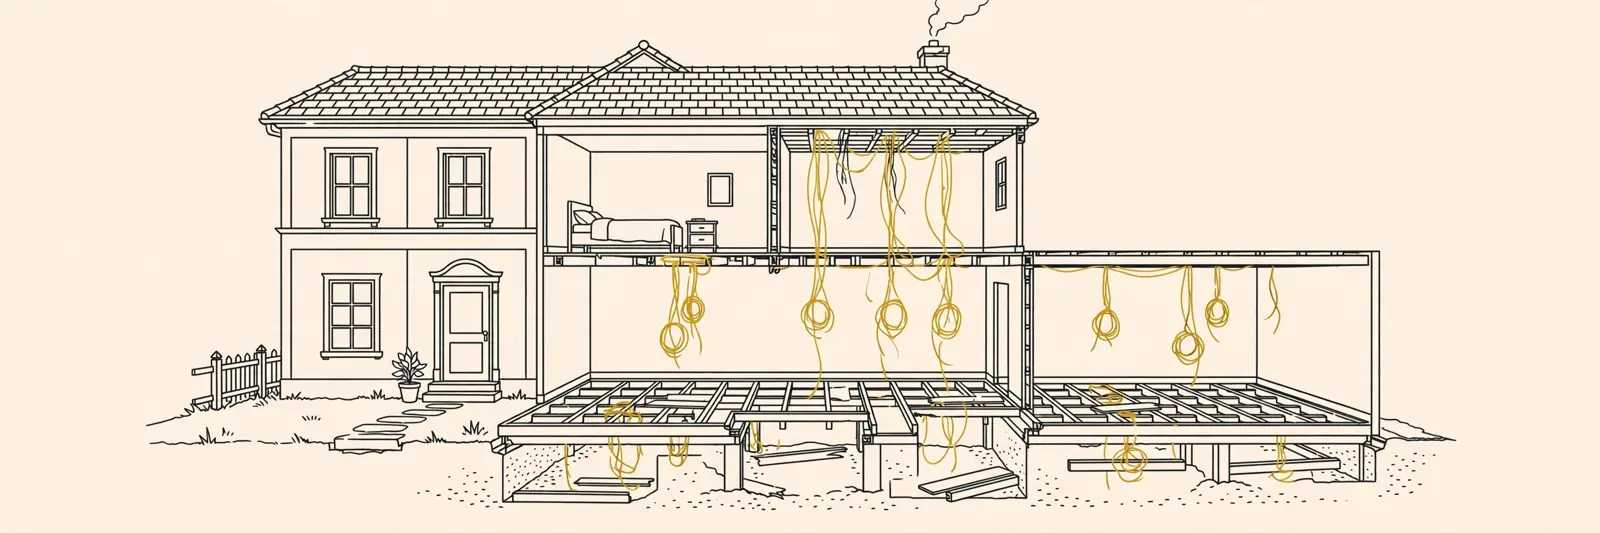
The most quotable version of the warning comes from inside the industry. Michael Truell, the CEO of Cursor, has compared building on unreviewed AI output to putting up a house's walls and roof without checking the floorboards or the wiring: it stands, until it does not. "If you close your eyes and you don't look at the code and you have AIs build things with shaky foundations," he said, "as you add another floor, things start to kind of crumble." When the person selling the tool says the foundations are your job, believe him.
None of this cancels the scoreboard at the top of this article. It explains it. The winners so far use AI generation where it is strong, greenfield work, prototypes, well-tested paths, and they spend the saved time on the unglamorous parts: access rules, tests, review, and knowing what their own code does. The state of AI code generation in 2026 is not "it works" or "it doesn't." It is a power tool with a documented injury rate, and the craft is in the guardrails.
The meter is running: what all this costs
One more piece of the real state of things is the bill. The first generation of these tools was sold like ordinary software: a seat price, roughly $10 to $39 a month across Copilot's tiers, effectively unlimited within reason. Agentic tools broke that model, because an agent that works for an hour consumes an hour of computing, and somebody pays for every token it reads and writes along the way. In 2026 GitHub moved Copilot to usage-based billing, charging for consumption the way cloud providers charge for servers. The direction across the industry is the same: from renting a seat to metering a workforce.
This quietly changes the management question. While generation was a flat fee, more code felt free, and teams optimized for output. On a meter, an agent that loops all afternoon down the wrong path produces a real invoice, and the scarce resource turns out to be the one it always was: human attention, for direction at the start and review at the end. Which is why the teams getting durable value from these tools increasingly behave like firms managing a very fast, very literal junior workforce. Their habits are not mysterious, and they are worth stating plainly:
- Small batches. Ask for one feature at a time, so the change you have to review still fits in a human head.
- Tests before trust. Automated tests are the only reviewer that never gets tired, and they are what the agent loop aims at. No tests, no loop worth running.
- Read the diff where it counts. Not every line, but every change touching sign-in, payments, and who can see whose data, because those are the places the failures in this article lived.
- Check every package. Confirm that each library the model suggests actually exists and is the genuine one, because slopsquatting is now a standing attack, not a curiosity.
- Measure outcomes, not feelings. Track cycle time, defect rates, and rework, the way METR would, because perceived speed and real speed parted company in the data above.
None of that is a reason to sit this boom out. It is the price list for joining it with your eyes open.
Why this belongs at Starvard
Starvard's job is to turn headlines into skills you can actually use. If this article convinced you that directing AI well is now a core professional skill, our AI course is the place to build the foundations, and our AI agents course goes deeper on the tools that write and run code on your behalf. And because every failure story above ends at the same place, someone who could not read the code they shipped, our Python course remains the highest-value insurance policy in this entire field. Generate fast. Learn faster.
Watch
- Andrej Karpathy, "How I use LLMs": youtube.com/watch?v=EWvNQjAaOHw. A two-hour, example-driven walkthrough of how the person who coined vibe coding actually works with these tools day to day, including a full segment on writing code with Cursor's Composer. It is the best calibration video available for what skilled use looks like.
Sources
- TechCrunch, "Vibe-coding startup Lovable raises $330M at a $6.6B valuation," December 18, 2025. Lovable's $100M ARR in eight months, the doubling to $200M, the funding round, and the 100,000 projects per day figure: techcrunch.com
- TechCrunch, "Vibe-coding startup Anything nabs a $100M valuation after hitting $2M ARR in its first two weeks," September 29, 2025. Source of the Replit figure, ARR growth from $2.8 million to $150 million in under a year: techcrunch.com
- WinBuzzer, "AI Coding: Anthropic Acquires JS-Runtime Maker Bun As Claude Code Hits $1 Billion Revenue," December 3, 2025. Anthropic's disclosure of Claude Code's $1 billion run rate six months after general availability: winbuzzer.com
- Digit, "Cursor CEO thinks vibe coding is the biggest threat to modern software." Cursor's $1 billion annualized revenue and $29.3 billion valuation, and Michael Truell's "shaky foundations" remarks: digit.in
- Snyk, "The Highs and Lows of Vibe Coding." Pieter Levels' flight simulator revenue and player numbers, and the Lovable row level security findings: snyk.io
- TS2.tech, "Anthropic News Roundup," December 2025. Summarizes Anthropic's internal study of 132 engineers, who reported using Claude in about 60% of their work with self-reported productivity gains of roughly 50%: ts2.tech
- METR, "Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity," July 10, 2025, with a February 2026 follow-up note. The 19% slowdown, the perception gap, and the limits METR itself places on the result: metr.org
- EvalAI Tools, "AI Coding Agents in 2026: Evidence, Real Commit Data and Workflow." A tabulation of the controlled-trial literature, including the 2023 GitHub Copilot experiment's roughly 56% speedup on a greenfield task: evalaitools.com
- Veracode, "We Asked 100+ AI Models to Write Code. Here's How Many Failed Security Tests," 2025 GenAI Code Security Report. The 45% failure rate, Java's 72%, the 86% cross-site scripting failure rate, and flat security across model generations: veracode.com
- Cloud Security Alliance, "Vibe Coding Security Debt: AI-Generated Vulnerabilities at Scale," 2026. CVE-2025-48757 and the 170 of 1,645 apps finding, the CSO Online agentic platform study, and the 19.7% hallucinated package rate behind slopsquatting: labs.cloudsecurityalliance.org
- Final Round AI, "5 Vibe Coding Failures That Prove AI Can't Replace Developers Yet." The Enrichlead story, drawn from the founder's own public posts in March 2025: finalroundai.com
- Sphere, "AI Code Audit: Diligence on AI-Generated Code." GitClear's 211 million line analysis, the copy-paste milestone, and the roughly eightfold rise in duplicated code blocks: sphereinc.com
- Stack Overflow Developer Survey 2025, AI section. The 66% "almost right" frustration and 45% debugging burden figures: survey.stackoverflow.co/2025/ai
- The Register, "GitHub Copilot on autopilot as community complaints persist," September 5, 2025. Reports Satya Nadella's statement on Microsoft's July 30, 2025 earnings call that GitHub Copilot had reached 20 million users: theregister.com
- Slashdot, reporting The Verge, "More Than a Quarter of New Code At Google Is Generated By AI," October 29, 2024. Sundar Pichai's Q3 2024 earnings call statement that over 25% of Google's new code was AI-generated, then reviewed and accepted by engineers: developers.slashdot.org
- AI2Work, "Google Says 75 Percent of Its New Code Is Now AI-Generated," April 2026. Pichai's progression from over 25% in October 2024, to nearly half in fall 2025, to 75% at Google Cloud Next on April 22, 2026: ai2.work
- PCWorld, "Microsoft claims 30% of new code is written by AI," April 30, 2025. Nadella's LlamaCon remarks that 20 to 30 percent of the code in Microsoft's repositories was written by software, stronger in Python than in C++: pcworld.com
- TechRepublic, "Microsoft CEO Nadella: 20% to 30% of Our Code Was Written by AI," April 2025. The full LlamaCon exchange, including Zuckerberg's prediction that about half of development would be done by AI within a year: techrepublic.com
- DORA (Google Cloud), "State of AI-assisted Software Development," 2025 report. Nearly 5,000 technology professionals surveyed; AI adoption associated with higher delivery throughput and with higher instability, summarized in the report's finding that AI acts as an amplifier of an organization's existing strengths and weaknesses: dora.dev
- METR, "Measuring AI Ability to Complete Long Tasks," March 19, 2025. The task-completion time horizon: the length of task, in human expert time, that frontier agents complete half the time has been doubling roughly every seven months since 2019: metr.org
- SWE-bench, Jimenez et al., 2023, and the official SWE-bench Verified leaderboard. The original paper's best model, Claude 2, resolved 1.96% of issues; leading Verified entries reached about 79% by late 2025: swebench.com
- Morph, "SWE-bench Pro Leaderboard." Notes that OpenAI stopped reporting SWE-bench Verified in February 2026 over contamination, and tracks the successor benchmarks: morphllm.com
- Tech Insider, "GitHub Copilot Pricing [2026]: From $0 to $39/mo." Copilot's seat price range and GitHub's 2026 shift to usage-based billing: tech-insider.org
- Every, "The Secrets of Claude Code From the Engineers Who Built It" (AI and I podcast). Boris Cherny and Cat Wu on how the agent loop and sub-agents work, woven into the machinery section above: youtube.com
- Inside The Build, "AI Made Developers Slower, Then Something Weirder Happened." A walkthrough of the METR trial and its February 2026 follow-up, woven into the speed section above: youtube.com